Tracking API Reliability Guide: How to Monitor Uptime, Data Freshness & Missed Updates after Go-Live
After go-live, monitor tracking API reliability at three separate layers: whether requests succeed, whether shipment information arrives within an acceptable delay, and whether updates reach your own systems without gaps. A successful API response does not prove that tracking data is fresh or that a customer notification was delivered. Give each layer its own metrics, alerts, and recovery procedure.
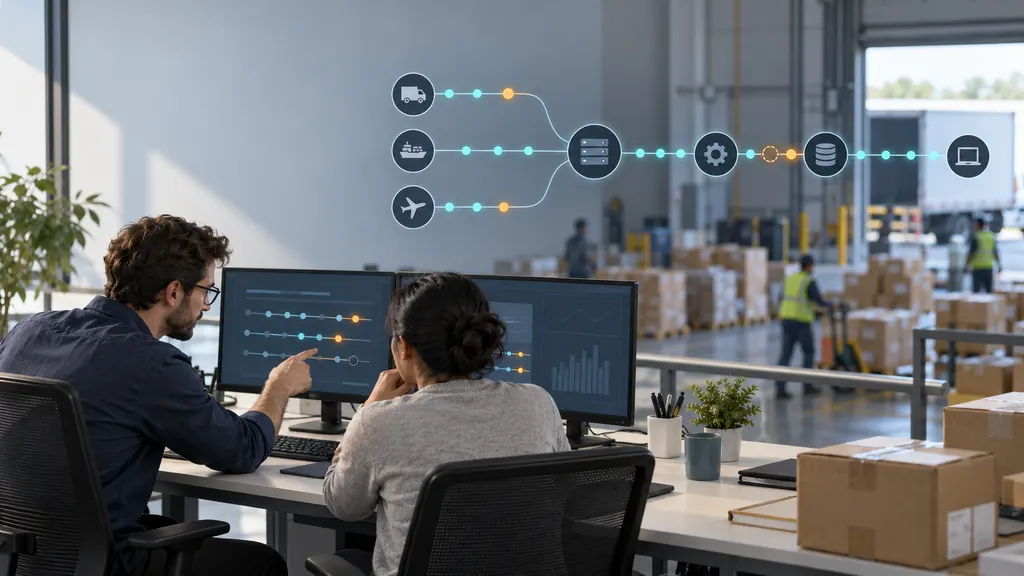
This guide is for engineers and operations teams responsible for a live shipment-tracking integration. The objective is to detect broken visibility before it becomes a support problem, then identify whether the failure sits with a carrier feed, the tracking provider, your webhook receiver, or downstream processing.
Define what a reliable tracking update means
Start with the complete delivery path: shipment registration, provider retrieval, API response or webhook delivery, internal processing, database persistence, and customer-facing display. If you send notifications, treat that as another stage rather than assuming a saved update reached the buyer.
For each stage, record its owner and the evidence that proves success. A provider accepting a tracking number proves registration was accepted, not that a carrier has published an event. A webhook receiving a successful HTTP response proves your endpoint acknowledged it, not necessarily that your worker committed the update.
Google's SRE guidance describes latency, traffic, errors, and saturation as the four golden signals of monitoring. Those signals are useful for your integration infrastructure, but shipment tracking also requires freshness and completeness checks because an apparently healthy endpoint can serve unchanged or incomplete information.
| Layer | Question to answer | Evidence to collect |
|---|---|---|
| API availability | Can the integration complete a valid operation? | Transport result, application result, latency, timeout rate |
| Data freshness | How far behind is the information? | Event time, observation time, receipt time, persistence time |
| Update completeness | Did every expected, retrievable update reach the destination? | Reconciliation differences, processing records, unresolved gaps |
| Customer visibility | Does the displayed status match the stored shipment state? | Read-path checks, cache age, notification processing results |
Instrument the integration before setting alerts
Keep an operational record that connects a shipment to its registration attempt, incoming updates, processing attempts, and resulting state. Use an internal shipment identifier for correlation; keep tracking numbers and customer details out of broadly accessible logs where possible.
The minimum useful record includes:
- Internal shipment ID, carrier identifier when known, integration account, and environment.
- Request or correlation ID, operation type, attempt time, result category, and duration.
- Provider event ID when supplied, plus the original event timestamp and timezone information.
- Webhook receipt time, durable storage time, processing completion time, and display availability time where measurable.
- Payload schema version when available, parsing result, deduplication result, and failure reason.
Preserve the original payload under appropriate access and retention controls when it is needed for investigation or replay. Do not log authorization headers or secrets. Use bounded dimensions such as carrier and result category for metrics; individual tracking numbers belong in searchable records, not high-cardinality metric labels.
Keep event time separate from observation time. The OpenTelemetry logs data model makes this distinction explicitly through Timestamp and ObservedTimestamp. Applying the same distinction to tracking records helps prevent a late-reported carrier event from being mistaken for a slow database write.
Monitor uptime from your application's point of view
Use both real production traffic and a low-volume synthetic check. Production traffic reveals actual customer impact. A synthetic check can detect failures when production traffic is quiet, provided it uses a documented, non-destructive operation and respects the provider's usage limits.
A useful request-success indicator is:
Successful eligible operations / All eligible attempted operations
Define “successful” using both HTTP status and the documented application-level result. Some interfaces can return a successful HTTP response while reporting a failed operation in the body. For batch operations, measure item-level outcomes as well as request-level outcomes.
Keep two views of failures. The customer-impact view includes anything that prevents your application from completing its task. The diagnostic view separates provider errors, network failures, authentication problems, invalid input, and quota or rate-limit responses. An expired credential may not be a provider outage, but it is still an outage for your integration.
- Latency: Track p50, p95, and p99 where traffic volume supports meaningful percentiles. Measure timeouts separately so fast failures do not make latency look healthy.
- Traffic: Compare request and callback volume with shipment registrations and the active shipment population.
- Errors: Separate transport failures, application failures, parsing errors, and downstream persistence failures.
- Saturation: Monitor connection pools, worker capacity, queue depth, oldest queued item, and available request budget.
Do not present these measurements as the provider's contractual uptime unless they use the contract's exact definitions. Your observed integration availability and a vendor's service-level agreement answer different questions.
Measure freshness without confusing silence with failure
A shipment that has not moved is not automatically stale. International transit, handoffs, weekends, and carrier scanning practices can produce legitimate gaps. The monitoring problem is to distinguish “nothing new happened” from “new information exists but our system has not received it.”
Use separate clocks for separate delays
- Latest-event age: Current time minus the latest carrier event time. This describes shipment visibility, not necessarily integration performance.
- Receipt delay: Your receipt time minus the event time. This includes upstream reporting and retrieval delays when intermediate timestamps are unavailable.
- Internal processing delay: Durable processing completion time minus receipt time. This isolates work inside your system.
- Display delay: Customer-facing availability time minus processing completion time. This can reveal cache or read-model problems.
- Verification age: Current time minus the last successful check for newer information. This measures checking activity, not proof that the carrier feed is current.
Only calculate provider-specific ingestion delay if the necessary provider timestamp exists and its meaning is documented. Without it, receipt delay cannot fairly be attributed to one party.
Normalize timestamps to a consistent timezone while preserving their original representation. Flag missing timezone information, future-dated events, and clock inconsistencies. Do not silently convert a negative delay to zero; investigate or classify it as a timestamp-quality issue.
Compare similar shipments
Build freshness views by carrier, service or route when known, shipment status, and time since registration. Separate newly registered shipments awaiting their first event from shipments already in transit. Exclude delivered shipments from active-movement checks according to your operational rules, while retaining any post-delivery monitoring your workflow requires.
Set initial thresholds from business requirements and observed behavior, not an invented universal refresh interval. A threshold suitable for local delivery may create noise for a cross-border handoff. Conversely, a broad network average can hide a problem affecting one carrier.
Label every freshness panel with its coverage. If event timestamps are missing for part of the population, show that population separately rather than making the remaining shipments appear representative of all traffic.
Find missed updates through reconciliation
Webhook volume alone cannot establish completeness. Quiet traffic may be normal, and a successful webhook response can conceal a downstream processing failure. Reconciliation compares what a reference source currently exposes with what your system has actually stored or processed.
- Define the eligible population. Include registered, actively monitored shipments. Track rejected registrations and paused monitoring separately so they do not disappear from operational reporting.
- Select a reference. Where the documented API permits it, retrieve current tracking details independently of webhook ingestion. Carrier tracking pages can help investigate individual cases, but should not become an automated scraping dependency without authorization.
- Apply a grace period. Allow for normal delivery and processing delays before classifying a difference as a suspected gap.
- Compare like with like. Match supported event identifiers, or use a documented normalization rule for timestamps, statuses, locations, and descriptions.
- Recover safely. Replay retained messages or fetch permitted updates through the normal idempotent processing path.
- Confirm the destination. Verify that the database and customer-facing view are corrected, not merely that a recovery job ran.
An internal indicator can be expressed as:
Eligible reconciled shipments with unresolved differences / All eligible reconciled shipments
Call this an unresolved reconciliation-gap rate, not a universal missed-event rate. If the reference exposes only the latest state, it cannot prove that every historical event arrived. Even a matching final status can conceal a missed intermediate milestone.
Start with a stratified sample across carriers, shipment ages, and statuses. Expand coverage for affected segments during an incident, subject to documented limits. Report both the number checked and the number with differences so a small sample is not mistaken for complete coverage.
Make webhook ingestion recoverable
Design the receiver to validate incoming requests and durably capture accepted messages before acknowledging them, consistent with the provider's documented delivery contract. Keep slower business logic in a separate worker where practical.
Verify the actual integration rules rather than assuming them: authentication or signature validation, acknowledgement requirements, request timeout, retry conditions, retry duration, ordering, and replay availability. These details determine what recovery your application must provide.
- Expect duplicates in your design: Use a documented event ID when available. Otherwise, create a carefully scoped deduplication key and test it against legitimate similar events.
- Handle out-of-order delivery: Preserve event history and use explicit transition rules instead of blindly replacing the shipment state with the last message received.
- Quarantine failures: Retain unprocessable messages with their error details and provide a controlled redrive process.
- Separate state recovery from side effects: Replaying an event should not automatically resend an old delivery email or repeat another customer-facing action.
If your integration uses 17TRACK, use the official Tracking API documentation as the implementation reference and check the requirements that apply to your integration. The Tracking API product page provides product context, but monitoring thresholds and recovery assumptions should come from documented behavior, your service agreement, and production measurements—not from product descriptions.
Turn dashboards into actionable alerts
Every alert should identify the affected population, likely failure stage, business impact, and first investigation step. A global “tracking is stale” alert rarely provides enough information to act.
| Signal pattern | First investigation | Primary owner |
|---|---|---|
| Requests fail across several carriers | Check credentials, networking, limits, and provider responses | Integration or platform on-call |
| Callbacks arrive but processing age grows | Inspect workers, database health, and quarantined messages | Application engineering |
| One carrier shows unusual freshness gaps | Compare cohorts and sample reference tracking records | Tracking operations with engineering |
| Stored state is current but display is old | Inspect caches, read models, and frontend retrieval | Customer-facing application team |
Use sustained breaches and minimum sample sizes to reduce noise. For availability and processing objectives, an error budget can help distinguish a brief anomaly from a failure consuming an unacceptable share of allowed errors. Keep carrier-data freshness objectives separate from objectives your engineering team directly controls.
Use a recovery runbook that proves completion
When an incident starts, establish the last known healthy point and preserve relevant records. Determine whether new registrations, incoming messages, processing, or display updates are affected. Then estimate the shipment population at risk rather than reporting only request counts.
Restore the failed stage, replay or re-fetch within documented limits, and run reconciliation against the affected population. Close the incident only after backlog age returns to normal, unresolved gaps are accounted for, and customer-facing state is checked. Record separately any historical updates that cannot be recovered.
Test this process with controlled failures: an unavailable receiver, malformed payload, worker outage, duplicate event, out-of-order event, and expired credential. A test passes when the team detects the problem, identifies its owner, recovers the data, and avoids duplicate side effects—not simply when the endpoint becomes reachable again.
FAQ
Can an API return successful responses while tracking information is stale?
Yes. Request success establishes that an operation completed under the interface's rules. It does not establish that a carrier published a new scan or that every downstream system processed the result. Monitor freshness and end-to-end processing separately.
How often should we reconcile shipments?
Choose a cadence based on the acceptable detection delay, active shipment volume, request budget, and documented limits. Use more frequent checks for operationally sensitive segments and a broader scheduled sweep for coverage. There is no single interval suitable for every carrier and workflow.
Does no webhook activity mean the integration is broken?
No. There may be no new events. Compare callback activity with the active shipment population, recent patterns, receiver health, and an independent retrieval check where supported. Alert on corroborating evidence rather than silence alone.
Should we poll continuously as a backup?
Not by default. Uncontrolled polling can consume request capacity without improving visibility. Use bounded reconciliation and incident-specific retrieval within documented limits. Confirm how polling and webhook delivery interact for your provider.
What should we send when escalating a suspected provider issue?
Include affected operation types, UTC time ranges, sanitized request IDs, response codes, representative shipment references through an approved secure channel, and the expected versus observed behavior. Explain which internal stages you have checked. Do not include credentials or unnecessary customer data.
Sources
- Google SRE: Monitoring Distributed Systems — the four golden signals and monitoring principles.
- OpenTelemetry: Logs Data Model — the distinction between event timestamps and observed timestamps.
- 17TRACK Tracking API documentation — the implementation reference for a 17TRACK integration.
- 17TRACK Tracking API — official product context.