How Post-Purchase Service Providers Can Manage Multi-Brand Tracking with One API
Post-purchase service providers can manage tracking for multiple ecommerce brands through one API by separating the shared shipment-data layer from each brand’s customer-facing experience. The practical model is a multi-tenant tracking service: one integration receives tracking requests and events, while tenant rules control authentication, branding, carrier behavior, notifications, and reporting. This approach reduces duplicated integrations, but it only works well when data ownership, shipment identity, carrier normalization, and operational controls are designed from the start.
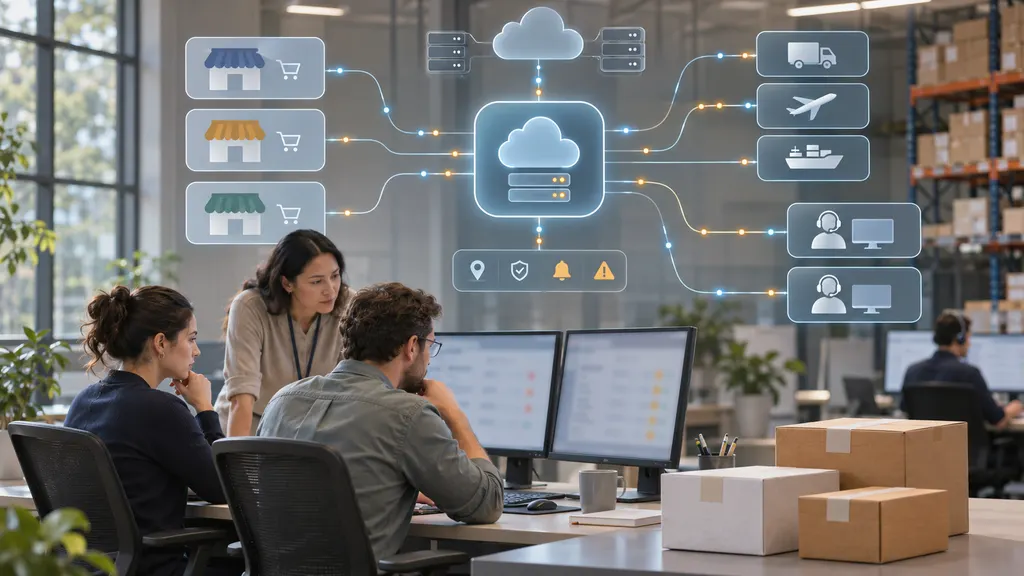
The goal is not simply to place several brands behind one endpoint. The goal is to give every client a reliable post tracking workflow without forcing the service provider to build and maintain a separate carrier connection for each brand. A well-designed system should make the shared infrastructure invisible to shoppers while giving operators enough control to investigate exceptions and protect data boundaries.
What “one API” should mean in a multi-brand model
In this context, one API usually means one provider-managed integration layer for multiple client brands. It does not necessarily mean that every customer receives the same response, interface, or notification journey. The API can expose a common contract while applying tenant-specific rules behind it.
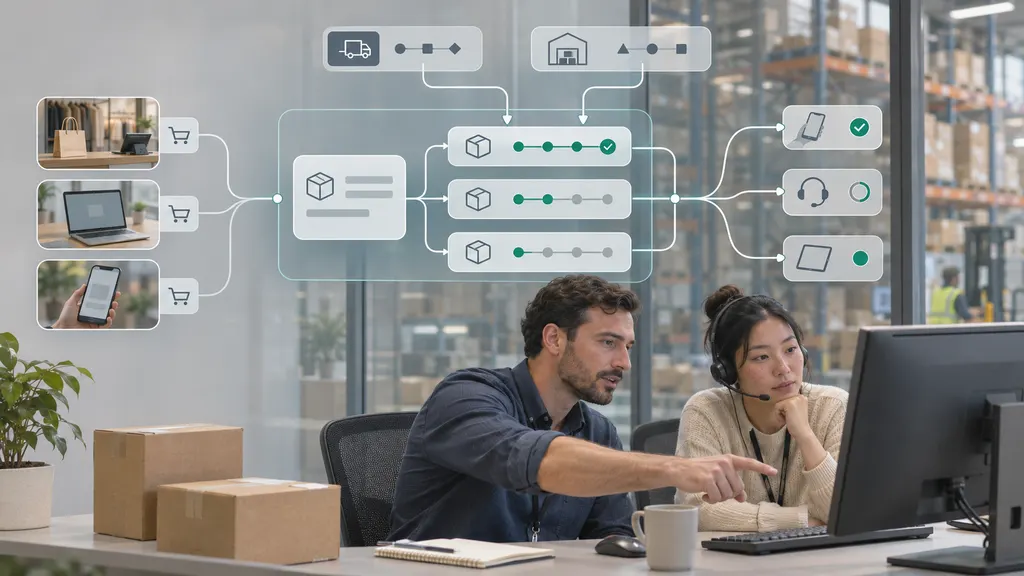
A typical request may include a tenant identifier, shipment or order reference, carrier information when available, tracking number, locale, and the requested operation. The service then authenticates the caller, determines which brand owns the shipment, submits or retrieves tracking data, normalizes the result, and returns a consistent response. The brand’s storefront, help center, order portal, or customer-service application can consume that response without needing to understand every carrier’s separate data model.
This model creates three boundaries that should not be confused:
- Integration boundary: how each client connects to the provider.
- Data boundary: which shipments, events, and customer references each client can access.
- Experience boundary: how each brand presents tracking, notifications, and support options to its buyers.
Keeping these boundaries explicit allows the provider to centralize the technical work while preserving brand-level control.
Start with a tenant-aware data model
The most important design decision is how the platform identifies a brand and its shipments. A tracking number alone should not be treated as the complete business identity of a shipment. The same reference may appear in different systems, and client applications may use order numbers, fulfillment IDs, or internal case IDs alongside carrier tracking numbers.
A safer model assigns each brand a stable tenant ID and stores shipment records with explicit ownership. Useful fields can include the tenant ID, shipment ID, order reference, tracking number, carrier code, destination region where appropriate, current status, event history, creation time, last synchronization time, and source system. The exact schema will vary, but ownership should be enforced at the API and database layers rather than relying only on the client interface.
Brand configuration should also be separated from shipment data. A configuration record might control the tracking-page domain, logo, supported languages, status wording, notification preferences, escalation rules, and customer-service links. This prevents operators from copying brand-specific logic into application code every time a new client is added.
For service providers, this separation has a second benefit: a carrier integration can be improved once and then used across eligible tenants. However, shared code should not imply shared permissions. A carrier connection may be common, while shipment visibility remains restricted to the tenant that submitted or owns the shipment.
Normalize carrier data before exposing it to brands
Multi-brand tracking becomes difficult when every carrier uses different event names, status logic, timestamps, and exception descriptions. One carrier may report a parcel as moving through the network, while another uses a more specific transport or facility event. Passing those raw values directly to every client creates inconsistent customer experiences and makes reporting difficult.
A shared normalization layer should map carrier-specific events into a controlled internal vocabulary. Common categories may include information received, in transit, available for pickup, out for delivery, delivered, delivery exception, and return-related events. The internal model should preserve the original carrier event as well as the normalized status. That allows the customer experience to remain simple without discarding diagnostic detail needed by support teams.
Normalization should also account for uncertainty. A platform should distinguish between a carrier-confirmed delivery event, a temporary lack of updates, and an inferred operational state. It should avoid converting an ambiguous carrier message into a definitive promise. If a carrier supplies an estimated delivery date, the API should identify it as an estimate rather than presenting it as a guaranteed appointment.
A provider such as 17TRACK can be evaluated as the shared tracking-data layer when the required carrier and API capabilities match the service provider’s use case. Its official API materials and developer documentation should be used to confirm supported operations, request formats, authentication, limits, and implementation requirements before production planning.
Design the API contract around operational use cases
A multi-brand API should be designed around what client systems need to do, not only around the data that a carrier happens to provide. At minimum, the contract should define how a client can create or register a tracking request, retrieve the current shipment state, obtain event history, and receive updates when the state changes if event delivery is part of the selected service.
The contract should document:
- How tenants and applications authenticate.
- Which identifiers are required and which are optional.
- How carrier codes are supplied, detected, or corrected.
- What a successful response means versus a request accepted for later processing.
- How unknown, delayed, duplicate, or conflicting events are represented.
- How pagination, retries, rate limits, and errors are handled.
- How webhook signatures, replay protection, and event ordering are managed if webhooks are used.
Idempotency is especially important. Clients may retry a request after a network timeout, and the platform should not create duplicate shipment records merely because the same request was submitted twice. Each tenant should also receive credentials with the narrowest practical scope. A brand’s application should not be able to query another brand’s shipment data by changing an identifier in a request.
Keep the shared data layer separate from the brand experience
One API does not require one tracking page. A service provider can use the same normalized data to support different customer experiences: a branded order-status page, an embedded widget, a customer-service console, or notifications managed by the client’s existing commerce platform.
The experience layer should decide how much information to show. A premium brand may display a detailed timeline and support link, while another client may prefer a compact status card. Both can consume the same underlying event model. This is also where language, time-zone presentation, brand terminology, and contact instructions belong.
For ecommerce providers, the order reference is often as important to the buyer as the tracking number. The API response should therefore make it possible to connect shipment status with the correct order without exposing unnecessary personal information. Customer-facing pages should use minimum necessary data, and operational dashboards should apply role-based access for agents, account managers, and administrators.
Build monitoring for the platform, not only for shipments
A shared tracking service has two monitoring problems. It must identify shipment-level issues, such as a delivery exception or an unusual period without an update, and platform-level issues, such as elevated API errors, delayed event processing, or a carrier connector that is returning incomplete data.
Metrics should be segmented by tenant, carrier, region, endpoint, and error type where the data supports it. Useful operational checks include request success rate, response latency, event-processing delay, duplicate-event rate, authentication failures, and the number of records requiring manual review. Segmentation matters because an aggregate platform metric can look healthy while one brand or carrier is experiencing a serious problem.
Create an escalation path before launch. Define who receives an alert, which evidence is attached, how a carrier issue is distinguished from a client-data issue, and when a customer-service team should be informed. A shared API should reduce operational fragmentation, not hide problems behind a single generic error message.
Use a controlled onboarding process for every brand
Adding a new brand should be a repeatable implementation process. Begin by mapping the client’s order, fulfillment, and customer-service systems. Confirm which shipment identifiers are available, which carriers are used, which regions require special handling, and whether the client wants the provider to manage notifications, only supply data, or support both.
- Define the tenant: create the brand record, credentials, roles, environments, and data-retention expectations.
- Map identifiers: document the relationship between orders, fulfillment records, tracking numbers, and customer-facing references.
- Test carrier inputs: use representative shipments across the brand’s main destinations and service types.
- Validate normalized statuses: compare API results with the carrier’s available tracking information and the client’s desired terminology.
- Test failure cases: include invalid numbers, delayed scans, duplicate requests, unknown carriers, returns, and partial shipment scenarios.
- Run a limited release: monitor real traffic for a controlled group before enabling the complete customer base.
- Document ownership: record who approves status wording, handles support escalations, and reviews platform changes.
This process also gives the provider a practical way to decide whether the existing one-API design is sufficient. If a client requires a carrier, data field, notification channel, or regional workflow that the shared layer cannot reliably support, that gap should be recorded and tested rather than hidden by a custom workaround.
Common failure modes to avoid
- Using brand names as security controls: display configuration is not a substitute for tenant authorization.
- Returning raw carrier statuses everywhere: this produces confusing customer language and inconsistent analytics.
- Assuming one tracking number equals one order: split shipments, replacements, and returns can change the relationship.
- Ignoring time zones: event timestamps should be stored consistently and presented in a way users can understand.
- Building notifications into the core data model: notification preferences should be configurable so different brands can use different channels and wording.
- Testing only successful deliveries: exceptions and missing updates are where support costs usually appear.
- Promising carrier coverage without verification: confirm the current carrier, region, and operation requirements in official documentation or a technical proof of concept.
A practical decision framework
A one-API approach is a strong fit when several brands share broadly similar shipment workflows, need consistent carrier data, and want the service provider to own integration maintenance. It is less straightforward when each client requires fundamentally different data contracts, strict regional isolation, or carrier-specific operational processes. Those requirements do not automatically rule out a shared platform, but they increase the need for configuration, testing, and clearly defined service boundaries.
Before selecting an API provider, run a proof of concept using real but controlled shipment examples. Test carrier identification, event normalization, update timing, error responses, authentication, tenant isolation, and the ability to retrieve the information needed by customer-service teams. Review the provider’s official multi-carrier tracking guidance and API documentation, then confirm any unresolved requirements directly. The right decision is not based on the number of carriers named on a marketing page; it is based on whether the provider can support the brands, destinations, workflows, and controls that the platform will actually operate.
Done well, one tracking API becomes a reusable operating layer rather than another isolated integration. It gives post-purchase service providers a consistent way to collect shipment updates, preserve brand-level experiences, and scale client onboarding without duplicating the same carrier work for every ecommerce account.
FAQ
Can one API serve several brands without sharing their data?
Yes, if tenant identity and authorization are enforced throughout the system. Each request should be associated with a permitted tenant, and shipment queries should be checked against that tenant before data is returned. Separate credentials, role-based access, audit logs, and isolation tests should be part of the implementation.
Should every brand use the same tracking page?
No. A shared API can provide normalized tracking data while each brand uses its own page, widget, language, terminology, and support links. Keeping presentation separate from the data layer makes multi-brand operations easier to manage.
What should be tested before production?
Test real-world carrier inputs, invalid tracking numbers, delayed events, duplicate requests, split shipments, returns, unknown carriers, webhook retries if applicable, and tenant-isolation controls. Also verify that normalized statuses match the language the client wants customers to see.
Does one API remove the need to manage carrier differences?
No. It centralizes much of the integration work, but carrier differences still need to be monitored and represented carefully. The provider should preserve useful raw event details while exposing a stable normalized model to client applications.
How should a provider evaluate a tracking API?
Evaluate the API against the provider’s actual brands, carriers, regions, event requirements, authentication model, limits, error handling, update behavior, and support process. A controlled proof of concept is more reliable than assuming that a general feature description covers every required workflow.