15 Questions to Ask a Tracking API Provider before Going to Production
Before putting a tracking API into production, ask how it handles your actual carriers and shipment types, what its events mean, how updates arrive, and what happens when data or the integration fails. The 15 questions below give engineering and operations teams a practical way to test those answers before customers, support agents, or automated workflows depend on them.
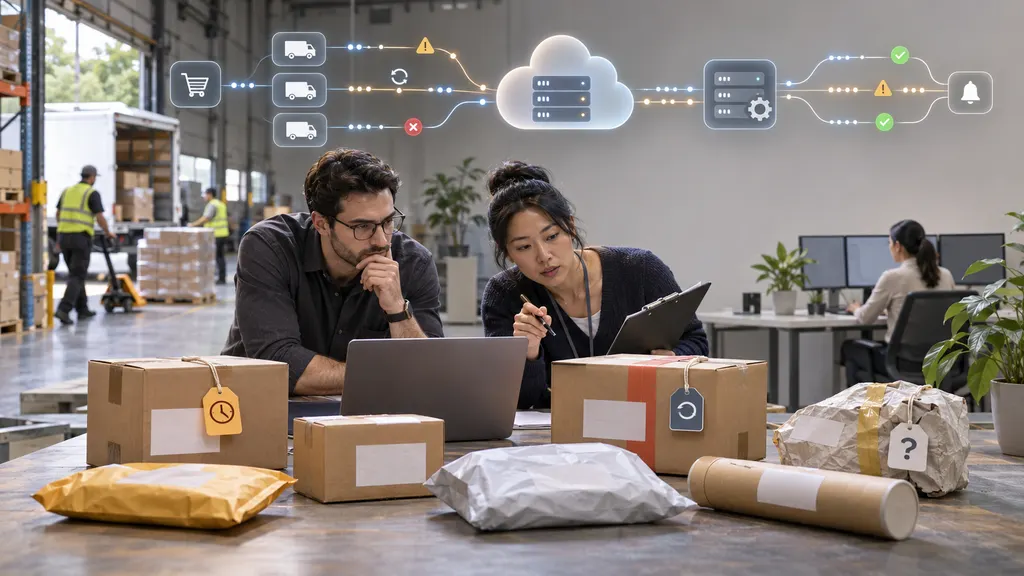
A successful demo is not a production test. Use a representative sample of shipments, including delayed, returned, and hard-to-identify parcels. For each answer, request documentation, a sample payload, or a test result. Record any unresolved item with an owner and a decision date rather than assuming it will be addressed after launch.
Start with shipment fit and data meaning
1. Which of our actual shipments can you track, and what does coverage mean?
Give the provider a sample of your carriers, services, origin and destination pairs, and tracking-number formats. Ask it to identify which shipments it can accept, which carriers it can identify automatically, and where you must supply a carrier code. A carrier appearing on a list does not establish that every service, handoff, or shipment type will produce the events your application needs.
Test real examples from high-volume lanes and operational edge cases. Include a shipment that changes carriers during transit if that occurs in your business. Record whether the API rejects a shipment, accepts it without finding events, or returns events with limited detail. Those outcomes require different handling in an order management system.
2. What is required to register a shipment, and how do you prevent duplicate registrations?
Clarify the required identifiers, carrier selection rules, registration timing, and response to an invalid or not-yet-active tracking number. Ask whether a tracking number alone is sufficient for your use case or whether additional information is needed. Confirm what happens if the same shipment is submitted twice, either by the same system or by separate services.
Build one registration flow with explicit ownership: which system submits shipments, which stores the provider’s identifier, and which retries an uncertain submission. If a request times out after the provider processes it, a blind retry must not silently create a second record or duplicate downstream notifications.
3. What do your statuses mean, and can we inspect the underlying carrier events?
Ask for a status dictionary and representative raw events. Terms such as in transit, out for delivery, exception, delivered, and returned are useful summaries, but your business rules may need more detail. Determine whether the provider supplies original carrier descriptions alongside standardized statuses, and how it handles an event that does not map cleanly.
Agree on your own internal status model before launch. In particular, decide which event can close a shipment, trigger a delivery message, or start an exception workflow. Do not treat a broad status label as proof of a specific physical event unless the underlying data supports that interpretation.
4. Which timestamps and locations are supplied, and how should we interpret them?
For each event, distinguish the time the carrier says it happened from the time the provider received or published it. Ask about time zones, missing offsets, location precision, and updates that arrive after later events. A recently received event may describe an older scan; sorting solely by ingestion time can produce a misleading timeline.
Test the payload against your database schema and customer-facing display. Decide how to show an event when its local time zone is uncertain, and avoid presenting a precise delivery time or location if the source does not provide one.
5. How are exceptions, returns, and proof of delivery represented?
Request examples of failed delivery attempts, customs holds, address problems, return-to-sender movements, and delivered shipments. Ask which details are standardized, which remain carrier-specific, and whether delivery confirmation includes any supporting evidence in the cases you care about. Do not assume a delivered status includes a recipient name, signature, photo, or other proof.
Map each exception to an action owner. Some events warrant a support review; others require no customer message until more information arrives. If proof of delivery is necessary for a dispute workflow, make its availability and format a separate acceptance criterion rather than an implied part of tracking coverage.
Test how updates reach your systems
6. Do you deliver updates by webhook, polling, or both, and when should we use each?
Ask for the documented delivery model, payload examples, subscription setup, and guidance for recovering missed updates. If webhooks are offered, determine whether they announce a changed shipment, provide a complete snapshot, or carry an individual event. If polling is required or used as a fallback, clarify the appropriate request pattern and how to identify changed records.
Choose the model based on the workflow. A customer-facing timeline may tolerate a different update delay than an exception queue. Your architecture should not promise instant alerts merely because an integration uses webhooks: the carrier must first make the event available, and each subsequent system must process it.
7. What happens when notifications are duplicated, delayed, or arrive out of order?
Ask whether the provider retries unsuccessful deliveries, for how long, and what response it expects from your endpoint. Request a stable event or shipment identifier if one is available. Then test the same notification twice, send an older event after a newer one, and temporarily return an error from your endpoint.
Your receiver should be designed to acknowledge only what it has safely accepted, process retries without repeating customer messages, and rebuild a correct timeline when events arrive out of order. If a proposed design depends on exactly one delivery of every notification, challenge that assumption before release.
8. How will we measure data freshness, and what affects it?
Ask what the provider can measure at each stage: carrier event time, provider ingestion time, and delivery time to your system. Separate those measurements from any commitment it makes. A long gap between the physical movement and your application’s update may originate upstream, within the provider’s processing, or inside your own queue.
During a pilot, measure these gaps for representative shipments and investigate outliers. Set alert thresholds against what your workflow actually requires. If a delayed scan would cause a harmful customer message or missed escalation, define a fallback such as a stale-data label or manual review.
9. How are API credentials and webhook requests protected?
Request the authentication and credential-management documentation. Confirm how credentials are issued, scoped, rotated, and revoked; whether test and production credentials are separate; and how a webhook receiver can verify that a request is authentic. Also ask what protections are available against replayed webhook requests.
Have your security team review the proposed implementation, not just the provider’s feature list. Keep secrets out of client-side code and logs, restrict access to production credentials, and rehearse credential rotation. If your application cannot verify an incoming notification with the documented mechanism, that is a release blocker for a webhook-based workflow.
10. What shipment and customer data do you retain, and where does it go?
List every field your integration would send, including tracking numbers, order references, addresses, contact details, and any custom metadata. Ask which fields are required, how long data and logs are retained, how deletion requests work, and which regions or subprocessors are relevant to your organization’s requirements. Obtain contractual or security documentation where your review requires it.
Minimize the data you transmit. A tracking integration should not receive customer information simply because it is convenient to pass an entire order object. Your privacy, legal, and security teams should decide whether the provider’s documented handling fits the markets in which you operate.
Plan for failure and operational change
11. What are the rate limits, and how should clients respond to errors?
Ask for limits by endpoint, credential, and environment, along with any concurrency rules and recommended retry behavior. Distinguish an invalid request from a temporary service problem and from a request that has been rate-limited. For HTTP APIs, status-code meanings matter: RFC 6585 defines 429 for too many requests, while RFC 9110 describes HTTP semantics, including server errors.
Calculate expected traffic for ordinary days and bursts, then test a client that backs off, queues work, and alerts on sustained failures. Confirm whether an uncertain write can be safely retried. A retry policy that multiplies traffic during an outage can make recovery harder.
12. How are schema, status, and carrier-integration changes communicated?
Ask about API versioning, deprecation notices, changelogs, and whether event fields can be added without a version change. Carrier-provided descriptions and tracking behavior can also change. Determine how the provider communicates a change that affects one carrier or route rather than the entire API.
Write tolerant parsers for optional fields and unknown status values, but do not quietly turn an unfamiliar value into delivered or failed. Store enough source detail to diagnose a changed mapping. Assign someone to review provider notices and update your integration tests before a change reaches customers.
13. What can we test before production, and how closely does the test environment match live behavior?
Request access to documentation, a test environment if offered, sample responses, and a way to exercise error paths. Ask which scenarios are simulated and which require live shipments. A sandbox may prove that your code handles a payload while saying little about carrier event completeness, update timing, or regional fit.
Run two kinds of tests: deterministic integration tests for parsing, retries, and security; and a limited live-shipment pilot for operational behavior. Include duplicate submissions, a provider timeout, a delayed scan, a return, and an unknown status. Require both engineering and the team that will act on exceptions to sign off on the results.
14. What support and incident commitments apply when tracking stops updating?
Ask which support channels are available to your account, how incidents are reported, and what contractual service commitments—if any—apply to the API or notification delivery. Clarify whether an uptime commitment covers the API endpoint, the delivery of tracking updates, or both. They are not the same operational outcome.
Establish your own runbook: who detects a failure, who contacts the provider, when polling or another fallback is used, and what customers see while updates are delayed. Request the process for resolving a shipment-specific data problem as well as a platform-wide outage. Test your escalation path before you need it.
15. How are usage and costs calculated, and what happens if we leave?
Ask which actions count toward billing or usage limits: submissions, tracked shipments, requests, notifications, or another unit. Confirm how duplicate registrations, retries, inactive shipments, overages, and test traffic are treated under the proposed agreement. Get the applicable terms in writing rather than estimating costs from an API demo.
Also plan for termination. Determine how you can export shipment histories, how long access remains available, and what happens to active tracking records. A workable exit plan is not a prediction that you will switch providers; it is a way to avoid losing visibility into shipments already in motion.
Turn the answers into a production decision
A useful go-live review has three outputs:
- A shipment-fit result: a tested sample showing which tracking records were accepted and whether their events support your intended customer and operations workflows.
- An integration result: demonstrated handling of authentication, duplicates, retries, delayed events, schema variation, and recovery from missed updates.
- An operating agreement: documented limits, data-handling terms, support contacts, cost assumptions, and owners for unresolved risks.
17TRACK is one provider to evaluate if a multi-carrier tracking API fits your use case; its Tracking API page and API documentation are starting points for checking the integration against these questions. The same standard should apply to any provider: documentation establishes how an interface is intended to work, while your own representative shipment tests establish whether it works for your production workflow. Do not release a customer notification or exception automation until the events that trigger it have been validated.
FAQ
Is a sandbox test enough to approve a tracking API for production?
No. A sandbox can validate request formats and some failure handling, but live shipments are needed to assess carrier-specific events, timing, and the usefulness of exception data on your actual lanes. Use both, with separate acceptance criteria.
Should we use webhooks or poll for tracking updates?
Use the provider’s documented delivery options and your workflow’s tolerance for delay to decide. Webhooks can reduce the need for repeated checks when supported, but your receiver still needs retry and duplicate handling. Polling may be appropriate as the primary method or as a recovery path, subject to documented limits.
What is the most common mistake in mapping tracking statuses?
Using one broad status as a trigger for a more specific business claim. For example, a delivered label alone may not provide the proof needed to resolve a dispute. Define triggers using the underlying event details your provider actually supplies.
Who should approve the integration before launch?
Engineering should approve reliability and security; operations or support should approve the usefulness of events and exception workflows; and the appropriate privacy, legal, and procurement owners should review data handling and commercial terms. Assign a named owner to any gap that remains open.