How Ecommerce Platforms Can Use Shipment Tracking Data to Flag Delivery Exceptions
Ecommerce platforms can flag delivery exceptions by combining carrier tracking events with order deadlines, shipment history, and rules for identifying problems. The most useful approach separates explicit carrier-reported problems from platform-detected risks, then routes each flag to someone who can act. A tracking update should become an operational alert only when the platform can explain what changed, why it matters, and what should happen next.
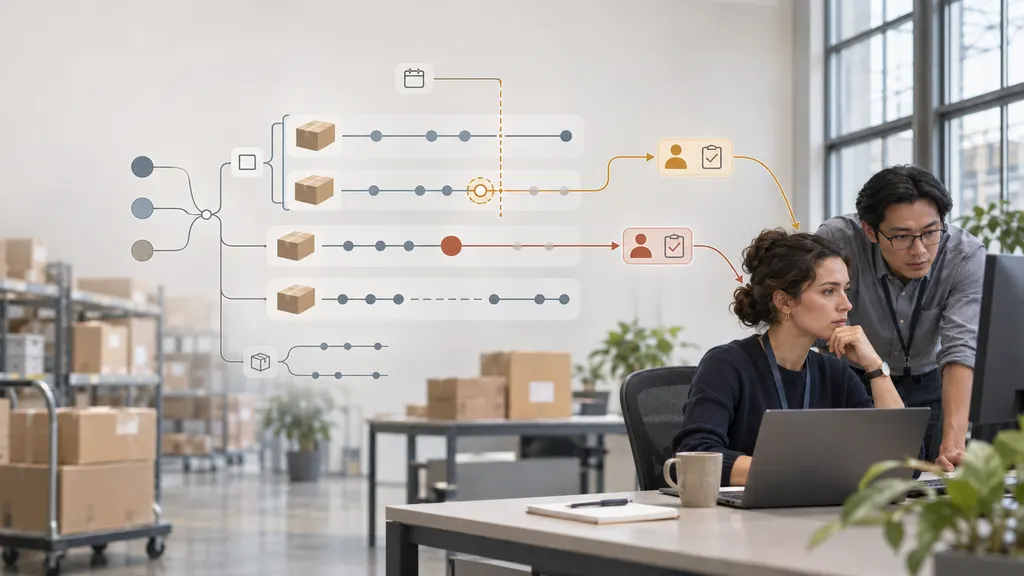
This guide focuses on the product, engineering, and logistics teams building that workflow. The objective is not to generate more alerts. It is to identify shipments that need intervention without treating every quiet tracking period as a failed delivery.
Separate carrier exceptions from delivery risks
A carrier-reported exception and a platform-generated risk flag are different types of information. Keep that distinction visible in the data model, staff dashboard, and customer messages.
- Carrier-reported exception: The source explicitly reports a problem, such as an unsuccessful delivery attempt or an address issue. Preserve the original wording because the required action may depend on the specific reason.
- Platform-detected risk: Your rules identify a possible problem, such as missing movement after an expected milestone. This is an inference, not confirmation that the parcel is delayed or lost.
- Delivery commitment breach: The shipment has not been confirmed delivered by the deadline associated with the order. This concerns the customer promise, which may differ from a carrier's estimated delivery date.
These categories can overlap. An address issue may appear before the promised delivery date, while an overdue shipment may still show an ordinary transit status. Store the categories separately rather than forcing all three into a single “exception” label.
Recommended operating principle: Use explicit events to trigger reason-specific workflows. Use inferred risks to trigger investigation, with uncertainty clearly stated.
Build a shipment record that can explain every flag
A latest-status field is not enough for dependable exception detection. The platform needs event history, order context, and a way to distinguish physical shipment inactivity from missing tracking data.
| Data group | Recommended fields | Why it matters |
|---|---|---|
| Shipment identity | Internal shipment ID, order ID, carrier, tracking number, package-to-item mapping | Links the alert to the correct parcel rather than the entire order by default. |
| Tracking evidence | Raw event text, source status, normalized status, event location, source event identifier when available | Supports classification while retaining the evidence behind it. |
| Time information | Event time, timezone or offset when provided, receipt time, last successful tracking refresh | Helps distinguish an old physical event from a late-arriving update. |
| Delivery context | Service, route, handover evidence, order delivery promise, carrier estimate when available | Provides context for deciding whether progress is abnormal. |
| Case state | Reason, confidence, severity, owner, next action, resolution condition | Turns detection into an accountable workflow. |
Treat missing fields as unknown, not as evidence of normal operation. If an event timestamp has no timezone, preserve that limitation instead of silently assigning a precise global timestamp.
Keep tracking identity separate from order identity. A split order can contain one delivered parcel and another awaiting movement. An order-level “delivered” state should not hide an unresolved package.
Normalize events without losing their meaning
Use a broad shipment status for navigation and a separate reason field for operational decisions. “In transit” can describe the shipment's overall stage while an address-related flag remains active.
A practical event-processing sequence is:
- Retain the source payload. Store enough original information to investigate mapping errors, subject to your security and retention requirements.
- Validate shipment association. Check that the event belongs to the expected shipment and carrier context.
- Deduplicate updates. Prefer source identifiers where available. Otherwise, define a conservative fingerprint using the shipment, event time, status, and location.
- Normalize status and reason. Map known source values into your taxonomy while retaining unknown values for review.
- Evaluate event order. A newly received event may describe something that happened before the current latest event.
- Recalculate applicable rules. Update the case state and record why a flag opened, changed, or closed.
Do not let a late-arriving transit scan automatically overwrite a newer delivery confirmation. At the same time, preserve a review path for corrections or contradictory evidence. Event precedence should be explicit and testable, not an accidental consequence of arrival order.
Start with rules that lead to a specific action
The following are recommended design patterns, not universal carrier definitions or service guarantees. Set timing thresholds using the service, route, operating calendar, and your own shipment history.
1. Shipment created, but handover is unconfirmed
Flag a fulfillment review when a shipment record exists but expected carrier acceptance evidence has not appeared after the merchant's handover deadline. First check whether the warehouse actually dispatched the parcel and whether tracking ingestion is working.
Owner: Fulfillment operations. Do not conclude: The carrier has lost the parcel. Shipment creation alone does not establish physical possession.
2. No meaningful movement within the expected window
Measure elapsed time since the last event that indicates meaningful shipment progress. Repeated copies of the same status should not automatically reset that clock.
Before opening a delivery-risk case, check source freshness and route context. A period without scans may reflect transport between facilities, a handoff, or a data problem rather than physical delay. Cross-border and domestic services should not automatically share the same inactivity threshold.
Owner: Logistics operations for shipment investigation; engineering or the integration team if data collection is failing.
3. An explicit problem requires intervention
When source data reports an address issue, unsuccessful attempt, or a request for information, create a reason-specific case. Route it according to who can resolve the blocker. A customer may need to confirm information, while a merchant or logistics partner may need to investigate.
Do not assume that every exception requires contacting the buyer. Read the source reason and any available instructions before selecting an action. Avoid promising redelivery or address changes unless those options are confirmed for the shipment.
4. The customer delivery deadline has passed
Evaluate the order's delivery promise separately from the carrier's current estimate. If the promised window has ended without confirmed delivery, create a customer-service risk flag even when tracking still reports transit.
Preserve the promise shown at purchase or agreed later. Replacing it with a moving estimate would make it harder to measure whether the original commitment was met.
5. Return movement or a delivery dispute needs review
Return-to-sender evidence should open a workflow distinct from an ordinary delay. Separately, a customer report of nonreceipt after a delivery scan should create a dispute case linked to the tracking evidence.
Do not automatically convert either event into a refund or replacement. Apply the merchant's verified policies and review the evidence. A delivery scan is relevant to an investigation, but it should not automatically close a customer-reported problem.
Make timing rules contextual and auditable
A single inactivity timer across all shipments is easy to implement but difficult to defend. Instead, group shipments by operationally meaningful characteristics, such as service, route, and shipment stage. Use historical observations to establish review thresholds where the data is sufficient.
Keep three clocks separate:
- Physical-event clock: Time since the latest meaningful shipment event.
- Data-freshness clock: Time since a successful tracking retrieval or expected update.
- Customer-promise clock: Time remaining until, or elapsed since, the agreed delivery deadline.
If data freshness fails, label the shipment's visibility as uncertain. Do not describe missing updates as proof that the parcel stopped moving. If many shipments from the same source become stale together, investigate a shared integration issue before opening separate logistics escalations.
Version your rules and record which version generated each flag. This makes it possible to explain past decisions and compare a revised threshold with the previous one.
Connect detection to case ownership and customer communication
Each active case should show the triggering evidence, reason category, confidence, severity, responsible team, next action, and resolution condition. Keep confidence separate from urgency: an inferred risk near a promised deadline may deserve prompt review even though its cause remains uncertain.
Group repeated events into the existing case when they describe the same unresolved problem. Send a new notification only when the situation or required action changes materially. Otherwise, repeated scans can produce duplicate tickets and confusing customer messages.
Customer communication should reflect what is known:
- Explicit source issue: Explain the reported problem and any verified next step.
- Inferred inactivity: Say that tracking has not shown a recent update and that the shipment is being checked.
- Missed delivery promise: Acknowledge the missed window without inventing a replacement date.
Close cases using reason-specific conditions. An unsuccessful-attempt case may move into a collection workflow rather than disappear. A technical data outage may be resolved while shipment-risk cases remain open. Preserve that separation.
Where a tracking integration fits
The tracking data connection supplies evidence; the ecommerce platform still needs rules that interpret that evidence against fulfillment deadlines, customer promises, and support policies.
For teams considering 17TRACK as a tracking data source, its Tracking API page and official API documentation are the relevant starting points for technical evaluation. Validate the actual response fields, status meanings, update-delivery options, and error behavior needed by your workflow before designing around them.
Use representative shipment samples during integration testing. Check whether the data lets you retain original events, associate parcels correctly, interpret timestamps, and distinguish source problems from transport problems. Do not assume that a tracking integration supplies your store's delivery promise or decides the appropriate customer remedy.
Test in shadow mode before automating interventions
Run new rules without customer-facing actions first. Have operations staff review a sample of flagged shipments and a sample of unflagged shipments. Reviewing alerts alone can reveal false positives, but it will not show which actionable problems the system missed.
Include duplicate events, out-of-order updates, missing timestamps, split shipments, handoffs, corrected statuses, and source outages in testing. Confirm that replaying an event does not create another case or send another message.
Measure actionable-alert rate, time to ownership, time to first action, duplicate-case frequency, and reviewed false positives. Segment results by rule and service where practical. Do not claim that an alert prevented a delivery failure merely because the shipment later arrived; that outcome does not establish causation.
Begin automation with reversible actions, such as internal routing and investigation requests. Expand customer notifications after message accuracy is established. Keep consequential decisions, including replacements or refunds, behind separately validated policies.
FAQ
Does a delivery exception mean a package is lost?
No. An exception can indicate a problem that needs attention without establishing loss. Preserve the reported reason and follow the applicable investigation process rather than translating every exception into “lost.”
How long should a platform wait before flagging missing tracking updates?
There is no reliable universal waiting period. Use the service, route, shipment stage, operating calendar, and observed history. Also check whether the tracking source is updating successfully before classifying the shipment as inactive.
Should every exception trigger a customer email?
No. Some flags require internal investigation, and others need no buyer action. Notify customers when there is a meaningful change, a verified action they can take, or a delivery commitment that needs to be addressed.
Can a platform detect exceptions using only the latest status?
It can identify some explicitly labeled problems, but it cannot reliably reconstruct elapsed inactivity, event sequence, or repeated attempts from a single status. Retain event history and order context for a more explainable workflow.
What is the safest first version to launch?
Start with a small set of explicit, actionable reasons and a separate overdue-promise rule. Run them in shadow mode, confirm ownership and resolution conditions, and add inferred-risk rules once data freshness and event processing are dependable.
Sources
- 17TRACK Tracking API — official entry point for evaluating the tracking integration discussed in this guide.
- 17TRACK API documentation — technical reference for checking integration requirements and data handling. The exception rules and operational workflows above are implementation recommendations, not claims that the API performs those decisions automatically.